Backprob through Layernorm
Equation for Layernorm:
, , .
As a computational graph:
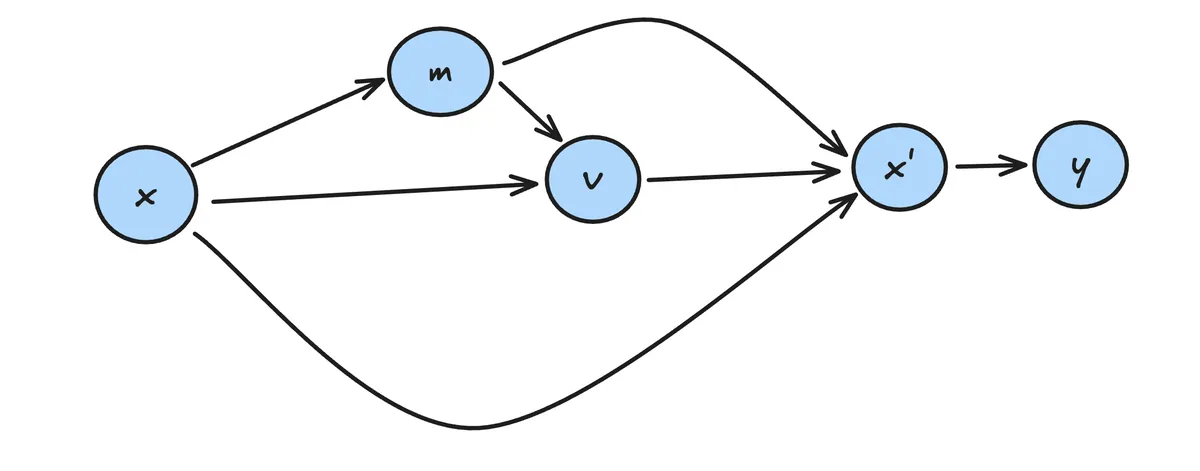
given.
Sum over all paths from to .
Plugging in:
has incoming paths from both and . Over the paths from we need to sum and sum these with the path from .
Plugging in:
Final backprop: Incoming from , and .
Calculate the terms separately.
First term:
Second term:
We can simplify this using definition of .
Last term
To summarise we have the three terms:
Now sum these up to obtain final result:
This is the formula given here.
    @staticmethod
    def backward(dout, cache):
        x, w, mean, rstd = cache
        # recompute the norm (save memory at the cost of compute)
        norm = (x - mean) * rstd
        # gradients for weights, bias
        db = dout.sum((0, 1))
        dw = (dout * norm).sum((0, 1))
        # gradients for input
        dnorm = dout * w
        dx = dnorm - dnorm.mean(-1, keepdim=True) - norm * (dnorm * norm).mean(-1, keepdim=True)
        dx *= rstd
        return dx, dw, db